-
Bug
-
Resolution: Fixed
-
 Medium
-
Upstream, Lustre 2.17.0, Lustre 2.16.1, Lustre 2.15.8
-
None
-
- EL 9.7 Servers
- Lustre 2.17.0
- 2 MDTs per Server
-
3
-
9223372036854775807
Affected Versions
Every release from 2.6.0 through 2.17.0, and current master. Introduced by commit 52d620153307 (“Backport shrinker changes from upstream”, 2014-04-24).
Problem
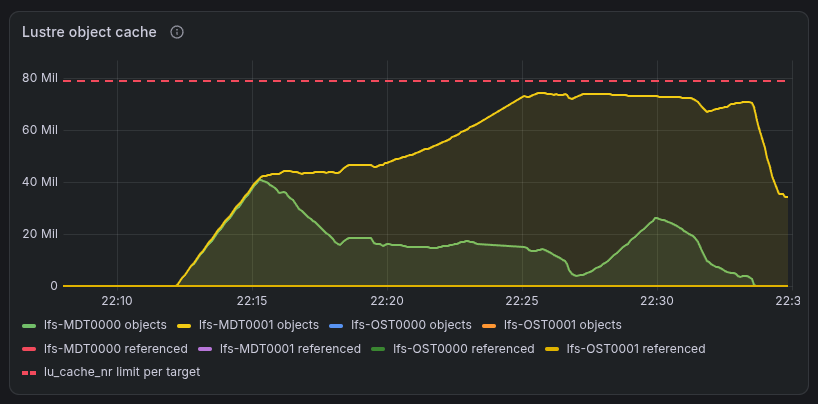
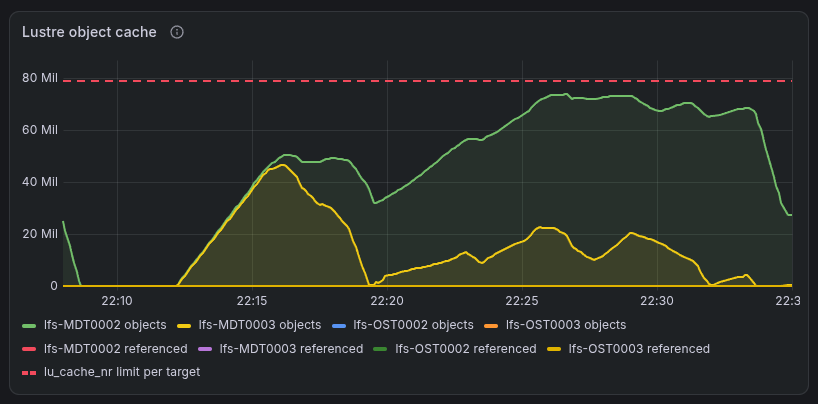
When a server holds several MDTs, the Lustre object-cache shrinker frees far more than the kernel asks for and always takes the excess from the same MDT, so one MDT per server is repeatedly emptied while its neighbour keeps a full cache.
Code issue
- lu_cache_shrink_scan() keeps visiting sites after remain reaches 0 and passes 0 to the next site.
- lu_site_purge_objects() with nr == 0 still takes one object per bucket (bnr = 0 / buckets + 1). Then --nr turns 0 into -1, the purge-all value, which it returns as the remainder. The next site is purged without limit.
- Visited sites are moved to the tail and spliced back in the same order, so the list never rotates. The same MDT gets the zero budget on every callback.
- The callback reports nr_to_scan + 1 freed while it freed up to 384.
Reproduction
MDS with two MDTs, 256 buckets per site:
echo "0 0 128" > /sys/kernel/debug/shrinker/lu_site-0/scan
One scan of 128 purged 128 objects from MDT0001 and 256 from MDT0000. Eight scans purged 1024 and 2048, and the budget never moved to another site.
Workload for the attached graphs
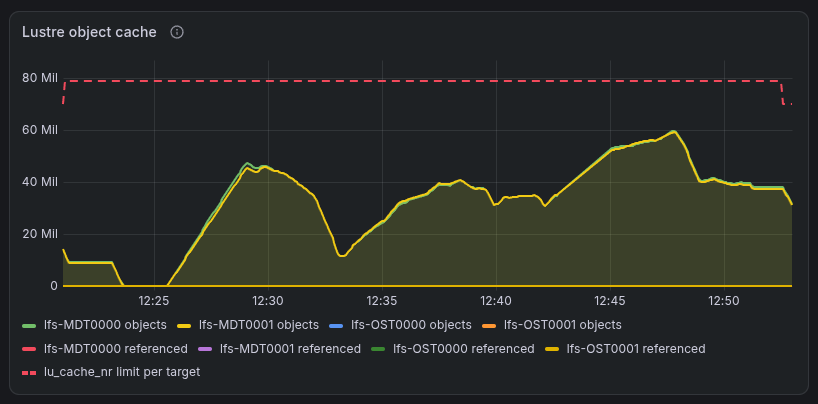
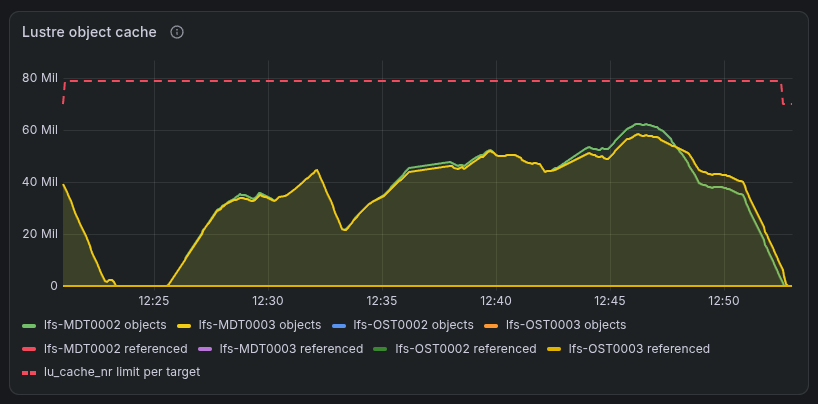
io500 mdtest-easy-stat and mdtest-hard-stat on an existing dataset of ~229 M + ~70 M files, 576 ranks (6 clients x 8 mounts), 4 ldiskfs MDTs on 2 MDS (two per server). Caches dropped once, then three passes back to back.
Without the fix, one MDT per server receives the zero budget on every callback and is drained, while its neighbour grows.
Fix
Stop the scan once the budget is used up, so unvisited sites stay at the head of the list. Return from lu_site_purge_objects() without purging when nr == 0. The -1 purge-all of explicit callers is unchanged.
With the fix (same workload, see attached graphs):
- One debugfs scan of 128 purges at most 128 objects. Eight scans split 512 / 512.
- The cache of both MDTs of a server stay equal.